About
The Cornell Phonetics Lab is a group of students and faculty who are curious about speech. We study patterns in speech — in both movement and sound. We do a variety research — experiments, fieldwork, and corpus studies. We test theories and build models of the mechanisms that create patterns. Learn more about our Research. See below for information on our events and our facilities.
Upcoming Events
16th November 2026 12:20 PM
PhonDAWG - Phonetics Lab Data Analysis Working Group
Melinda (Xinyi) will present her Q-paper experiment design and some preliminary data.
Location: B11 Morrill Hall, 159 Central Avenue, Morrill Hall, Ithaca, NY 14853-4701, USA
17th November 2026 07:00 PM
ASL Literature Series: Handplay with Vicki Nordquist
The ASL Program at the Department of Linguistics proudly presents Vicki Nordquist - an interactive performance with ASL storytelling, ABC stories, handshape stories, and comedy.
Vicki Nordquist is a retired educator from the Rochester School for the Deaf, where she worked with students from preschool through high school and often directed school plays. Vicki has also taught Sign Mime and holds a certificate in Clownology. Vicki’s interest in ASL began at the age of 10 and sparked her lifelong appreciation for reading, writing, and storytelling.
ASL/English interpretation will be provided.
Location: 106 Morrill Hall, 159 Central Avenue, Morrill Hall, Ithaca, NY 14853-4701, USA
18th November 2026 12:20 PM
Phonetics Lab Meeting
Faolan will lead a discussion of this paper by Keith Johnson - The ΔF method of vocal tract length normalization for vowels.
Abstract:
Given the acoustic consequences of physiological differences between talkers, there is a practical need for effective and theoretically motivated procedures of vowel normalization to facilitate comparison of speech produced by people who differ by dialect or language. In addition, there is a question whether listeners might utilize a normalization procedure during speech perception.
This paper reports the results of two studies that explore these questions—with particular focus on vocal tract length normalization. Drawing on research in speech engineering, where accurate estimates of vocal tract length are needed in some approaches to automatic speech recognition and speaker verification, a new model of vowel normalization is introduced.
The model uses a direct measure of average formant spacing (the ΔF) which can be used to measure vocal tract length. The acoustic consequences of vocal tract length differences are removed from vowel measurements by scaling vowel formant measurements by ΔF.
Study 1 found that this method is comparable to Nearey’s (1978) uniform normalization method, while providing an explicit vocal tract length interpretation, and a rationalized unit of measure.
Study 2 found that uniform normalization measures (which let each formant serve as a noisy estimator of ΔF) improve vowel classification even with only a couple of randomly selected vowel tokens.
This suggests that vocal tract length normalization could be involved in speech perception.
Location: B11 Morrill Hall, 159 Central Avenue, Morrill Hall, Ithaca, NY 14853-4701, USA
19th November 2026 04:30 PM
Linguistics Colloquium Speaker: Kyle Rawlins
The Department of Linguistics proudly presents Dr. Kyle Rawlins, Associate Professor and Director of Graduate Studies in the Cognitive Science Department at Johns Hopkins University.
Dr. Rawlins will give a talk titled: Rhetorical questions and moves
Funded in part by the GPSAFC and Open to the Graduate Community.
Abstract:
A rhetorical question is one that has the function, apparently, of conveying information:
(1) After all, what does Onavi know about semantics? (Example from Caponigro and Sprouse 2007)
Implies: Onavi knows nothing/very little about semantics
Since this is essentially the opposite of what is widely viewed as the canonical function of a question, i.e. requesting information, rhetorical questions have provided a valuable testbed for theories of questions, and discourse more broadly.
A recent popular view (Rohde 2006, Caponigro and Sprouse 2007, Biezma and Rawlins 2017) is that rhetorical questions are a limiting case of ordinary questions: questions whose answer is (or should be) apparent to agents in the discourse. Recent work from Farkas (2024) presents a number of challenges to this view, in the form of unresolvable rhetorical questions, and rhetorical questions like 'is the pope catholic?' when used as answers.
In this talk I show how to generalize the dynamics of rhetorical questions as ordinary questions in the face of these challenge cases, and provide new data showing that Farkas' prior generalization along these lines doesn't go far enough.
The proposal is that a question is rhetorical just in case the update sequence that agents would expect to happen based on public information (including answers or other means of dispensing with a question) would result in a non-inquisitive context.
Joint work with Dr. María Biezma (UMass Amherst)
Bio:
Kyle's research is primarily in three areas:
- Pragmatics and the semantics/pragmatics interface, often to do with the interpretation of questions.
- Compositional semantics and lexical semantics, especially involving the interfaces of the two.
- In computational semantics and natural language understanding. See also the Decompositional Semantics Initiative, and the MegaAttitude Project.
As part of many of these research projects, he has also been involved in the open release of various data sets.
Location: 106 Morrill Hall, 159 Central Avenue, Morrill Hall, Ithaca, NY 14853-4701, USA
Facilities
The Cornell Phonetics Laboratory (CPL) provides an integrated environment for the experimental study of speech and language, including its production, perception, and acquisition.
Located in Morrill Hall, the laboratory consists of six adjacent rooms and covers about 1,600 square feet. Its facilities include a variety of hardware and software for analyzing and editing speech, for running experiments, for synthesizing speech, and for developing and testing phonetic, phonological, and psycholinguistic models.
Web-Based Phonetics and Phonology Experiments with LabVanced
The Phonetics Lab licenses the LabVanced software for designing and conducting web-based experiments.
Labvanced has particular value for phonetics and phonology experiments because of its:
- *Flexible audio/video recording capabilities and online eye-tracking.
- *Presentation of any kind of stimuli, including audio and video
- *Highly accurate response time measurement
- *Researchers can interactively build experiments with LabVanced's graphical task builder, without having to write any code.
Students and Faculty are currently using LabVanced to design web experiments involving eye-tracking, audio recording, and perception studies.
Subjects are recruited via several online systems:
- * Prolific and Amazon Mechanical Turk - subjects for web-based experiments.
- * Sona Systems - Cornell subjects for for LabVanced experiments conducted in the Phonetics Lab's Sound Booth
Computing Resources
The Phonetics Lab maintains two Linux servers that are located in the Rhodes Hall server farm:
- Lingual - This Ubuntu Linux web server hosts the Phonetics Lab Drupal websites, along with a number of event and faculty/grad student HTML/CSS websites.
- Uvular - This Ubuntu Linux dual-processor, 24-core, two GPU server is the computational workhorse for the Phonetics lab, and is primarily used for deep-learning projects.
In addition to the Phonetics Lab servers, students can request access to additional computing resources of the Computational Linguistics lab:
- *Badjak - a Linux GPU-based compute server with eight NVIDIA GeForce RTX 2080Ti GPUs
- *Compute server #2 - a Linux GPU-based compute server with eight NVIDIA A5000 GPUs
- *Oelek - a Linux NFS storage server that supports Badjak.
These servers, in turn, are nodes in the G2 Computing Cluster, which currently consists of 195 servers (82 CPU-only servers and 113 GPU servers) consisting of ~7400 CPU cores and 698 GPUs.
The G2 Cluster uses the SLURM Workload Manager for submitting batch jobs that can run on any available server or GPU on any cluster node.
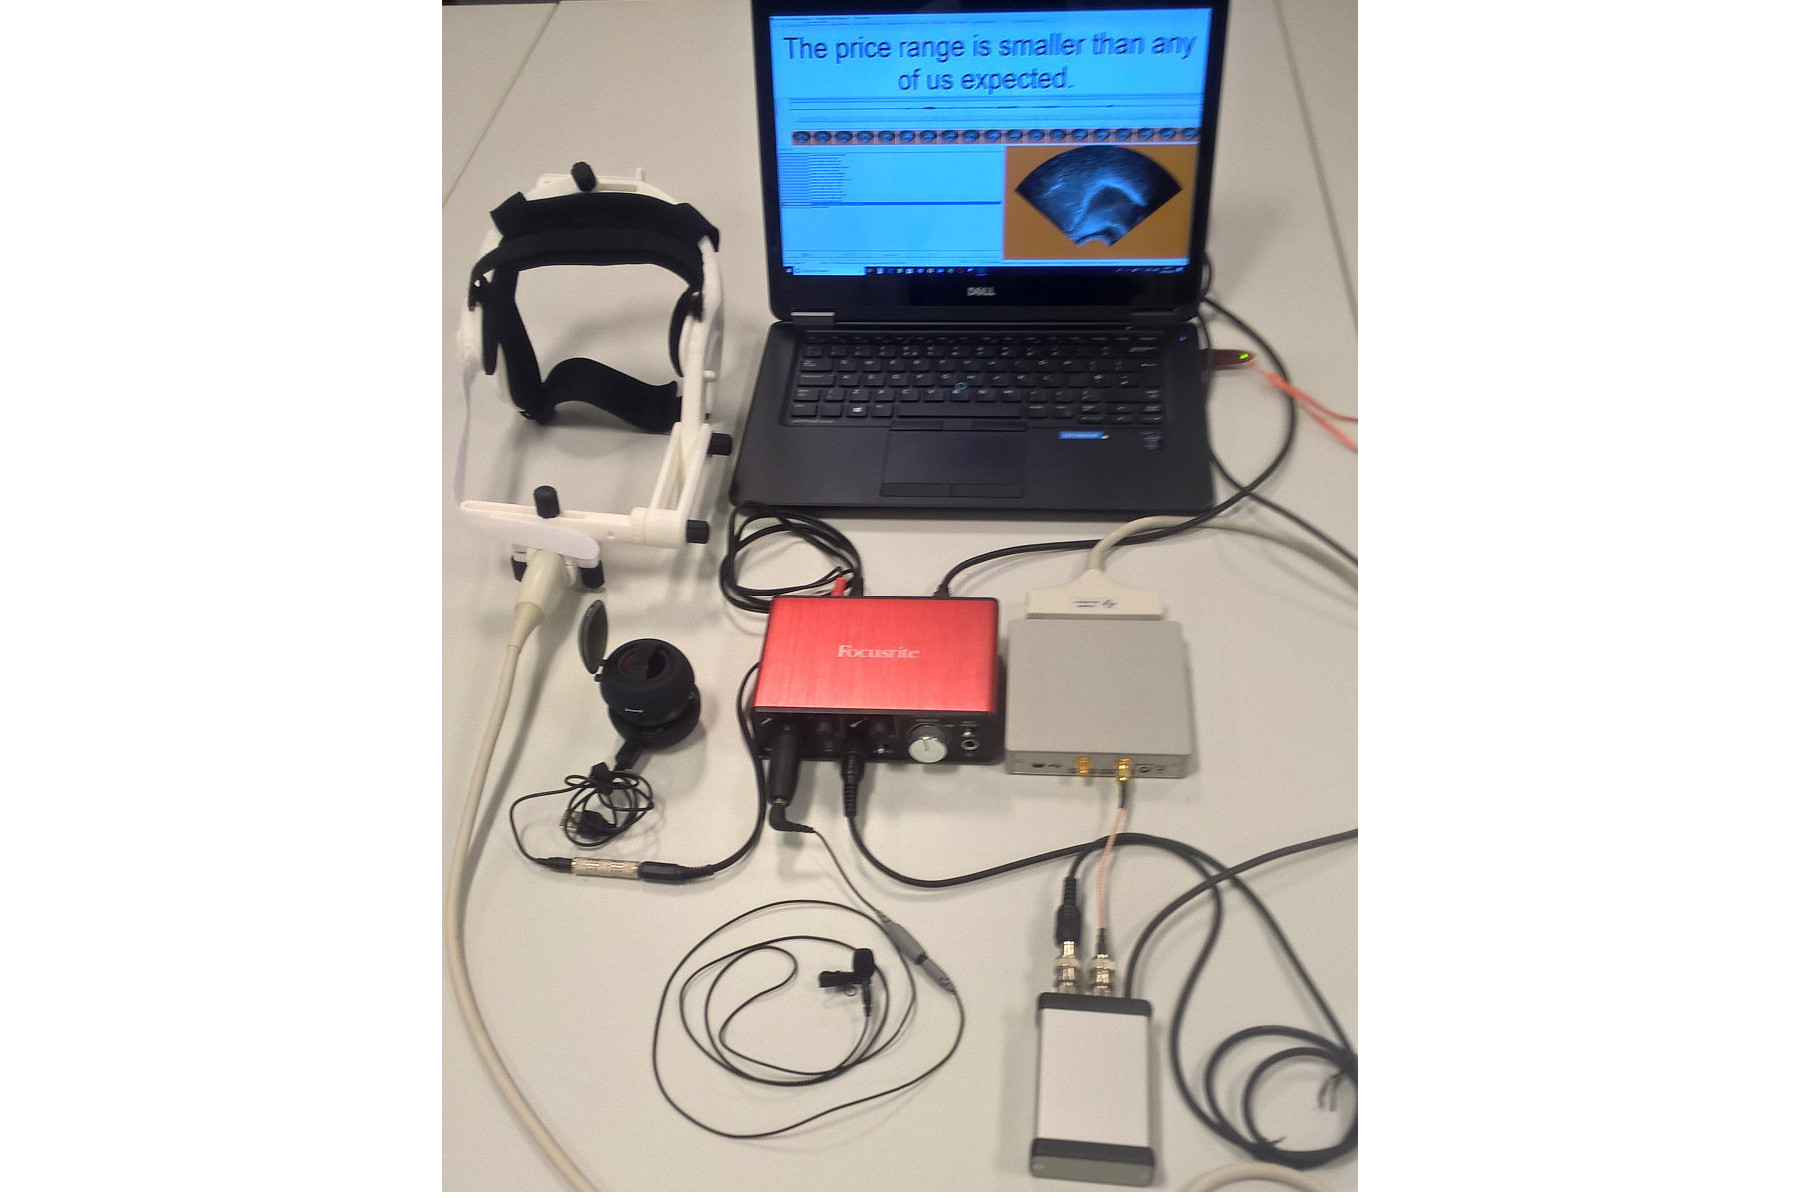
Articulate Instruments - Micro Speech Research Ultrasound System
We use this Articulate Instruments Micro Speech Research Ultrasound System to investigate how fine-grained variation in speech articulation connects to phonological structure.
The ultrasound system is portable and non-invasive, making it ideal for collecting articulatory data in the field.
BIOPAC MP-160 System
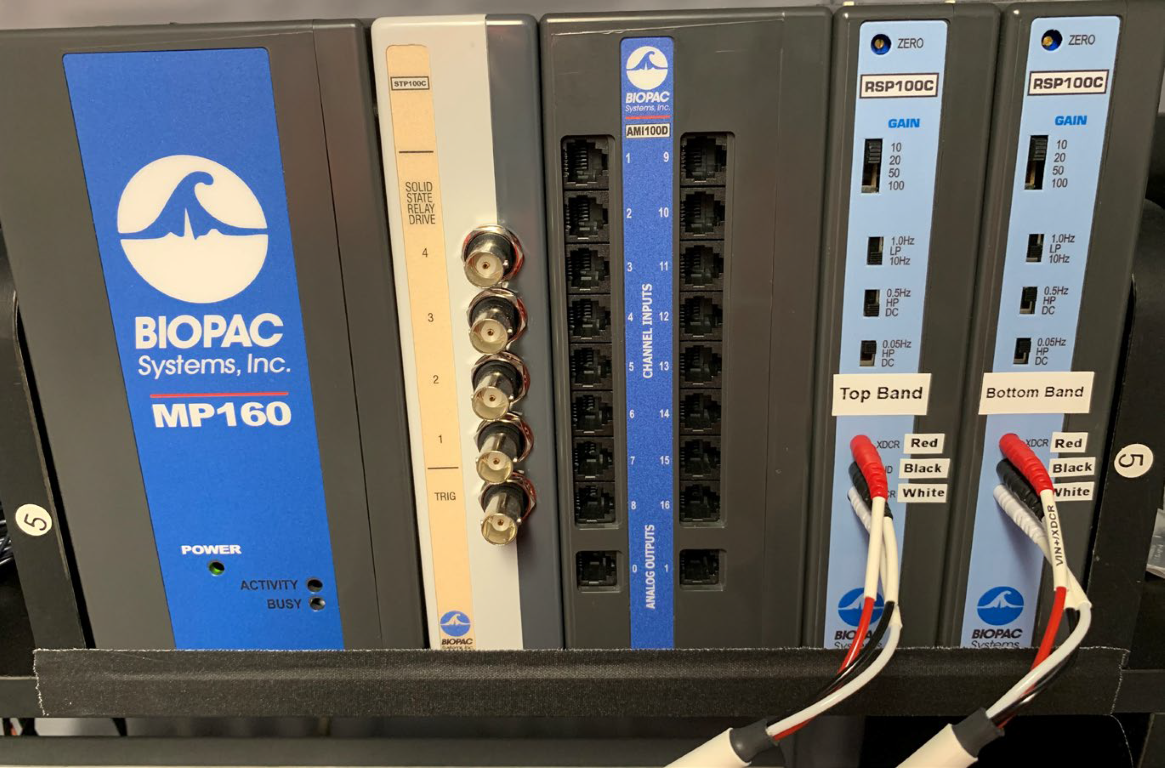
The Sound Booth Laboratory has a BIOPAC MP-160 system for physiological data collection. This system supports two BIOPAC Respiratory Effort Transducers and their associated interface modules.
Language Corpora
- The Cornell Linguistics Department has more than 915 language corpora from the Linguistic Data Consortium (LDC), consisting of high-quality text, audio, and video corpora in more than 60 languages. In addition, we receive three to four new language corpora per month under an LDC license maintained by the Cornell Library.
- This Linguistic Department web page lists all our holdings, as well as our licensed non-LDC corpora.
- These and other corpora are available to Cornell students, staff, faculty, post-docs, and visiting scholars for research in the broad area of "natural language processing", which of course includes all ongoing Phonetics Lab research activities.
- This Confluence wiki page - only available to Cornell faculty & students - outlines the corpora access procedures for faculty supervised research.
Speech Aerodynamics
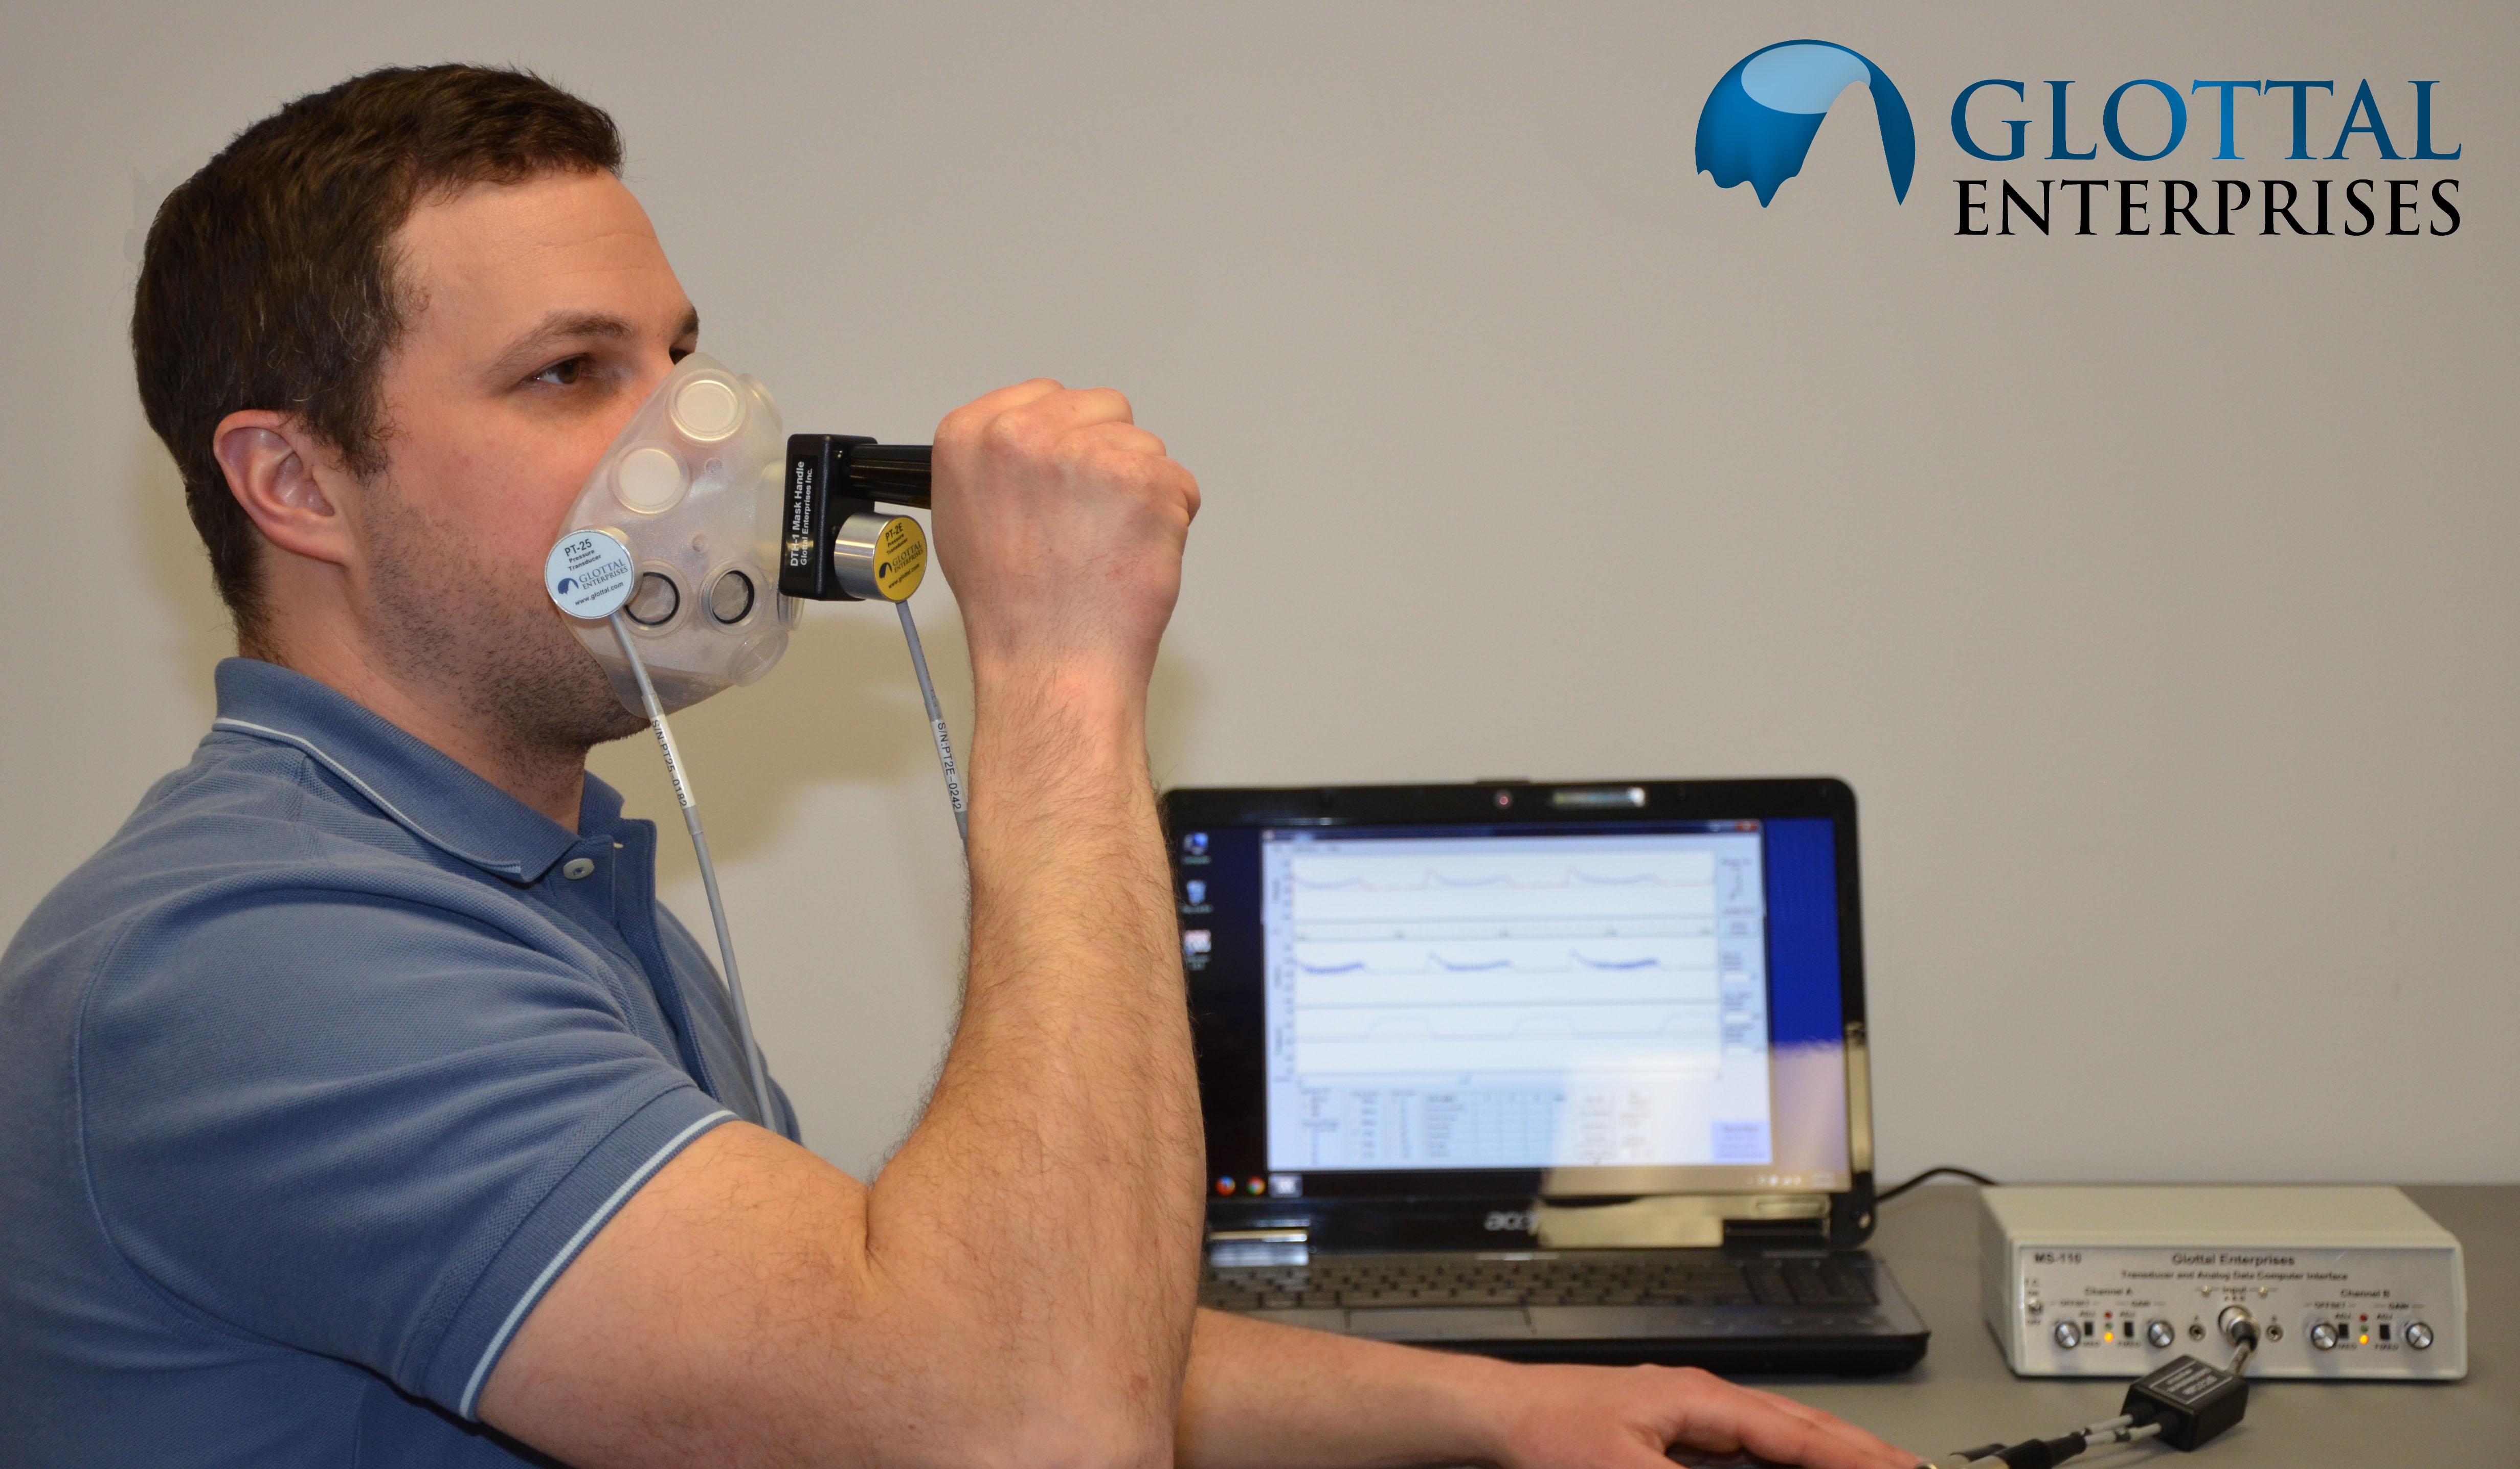
Studies of the aerodynamics of speech production are conducted with our Glottal Enterprises oral and nasal airflow and pressure transducers.
Electroglottography
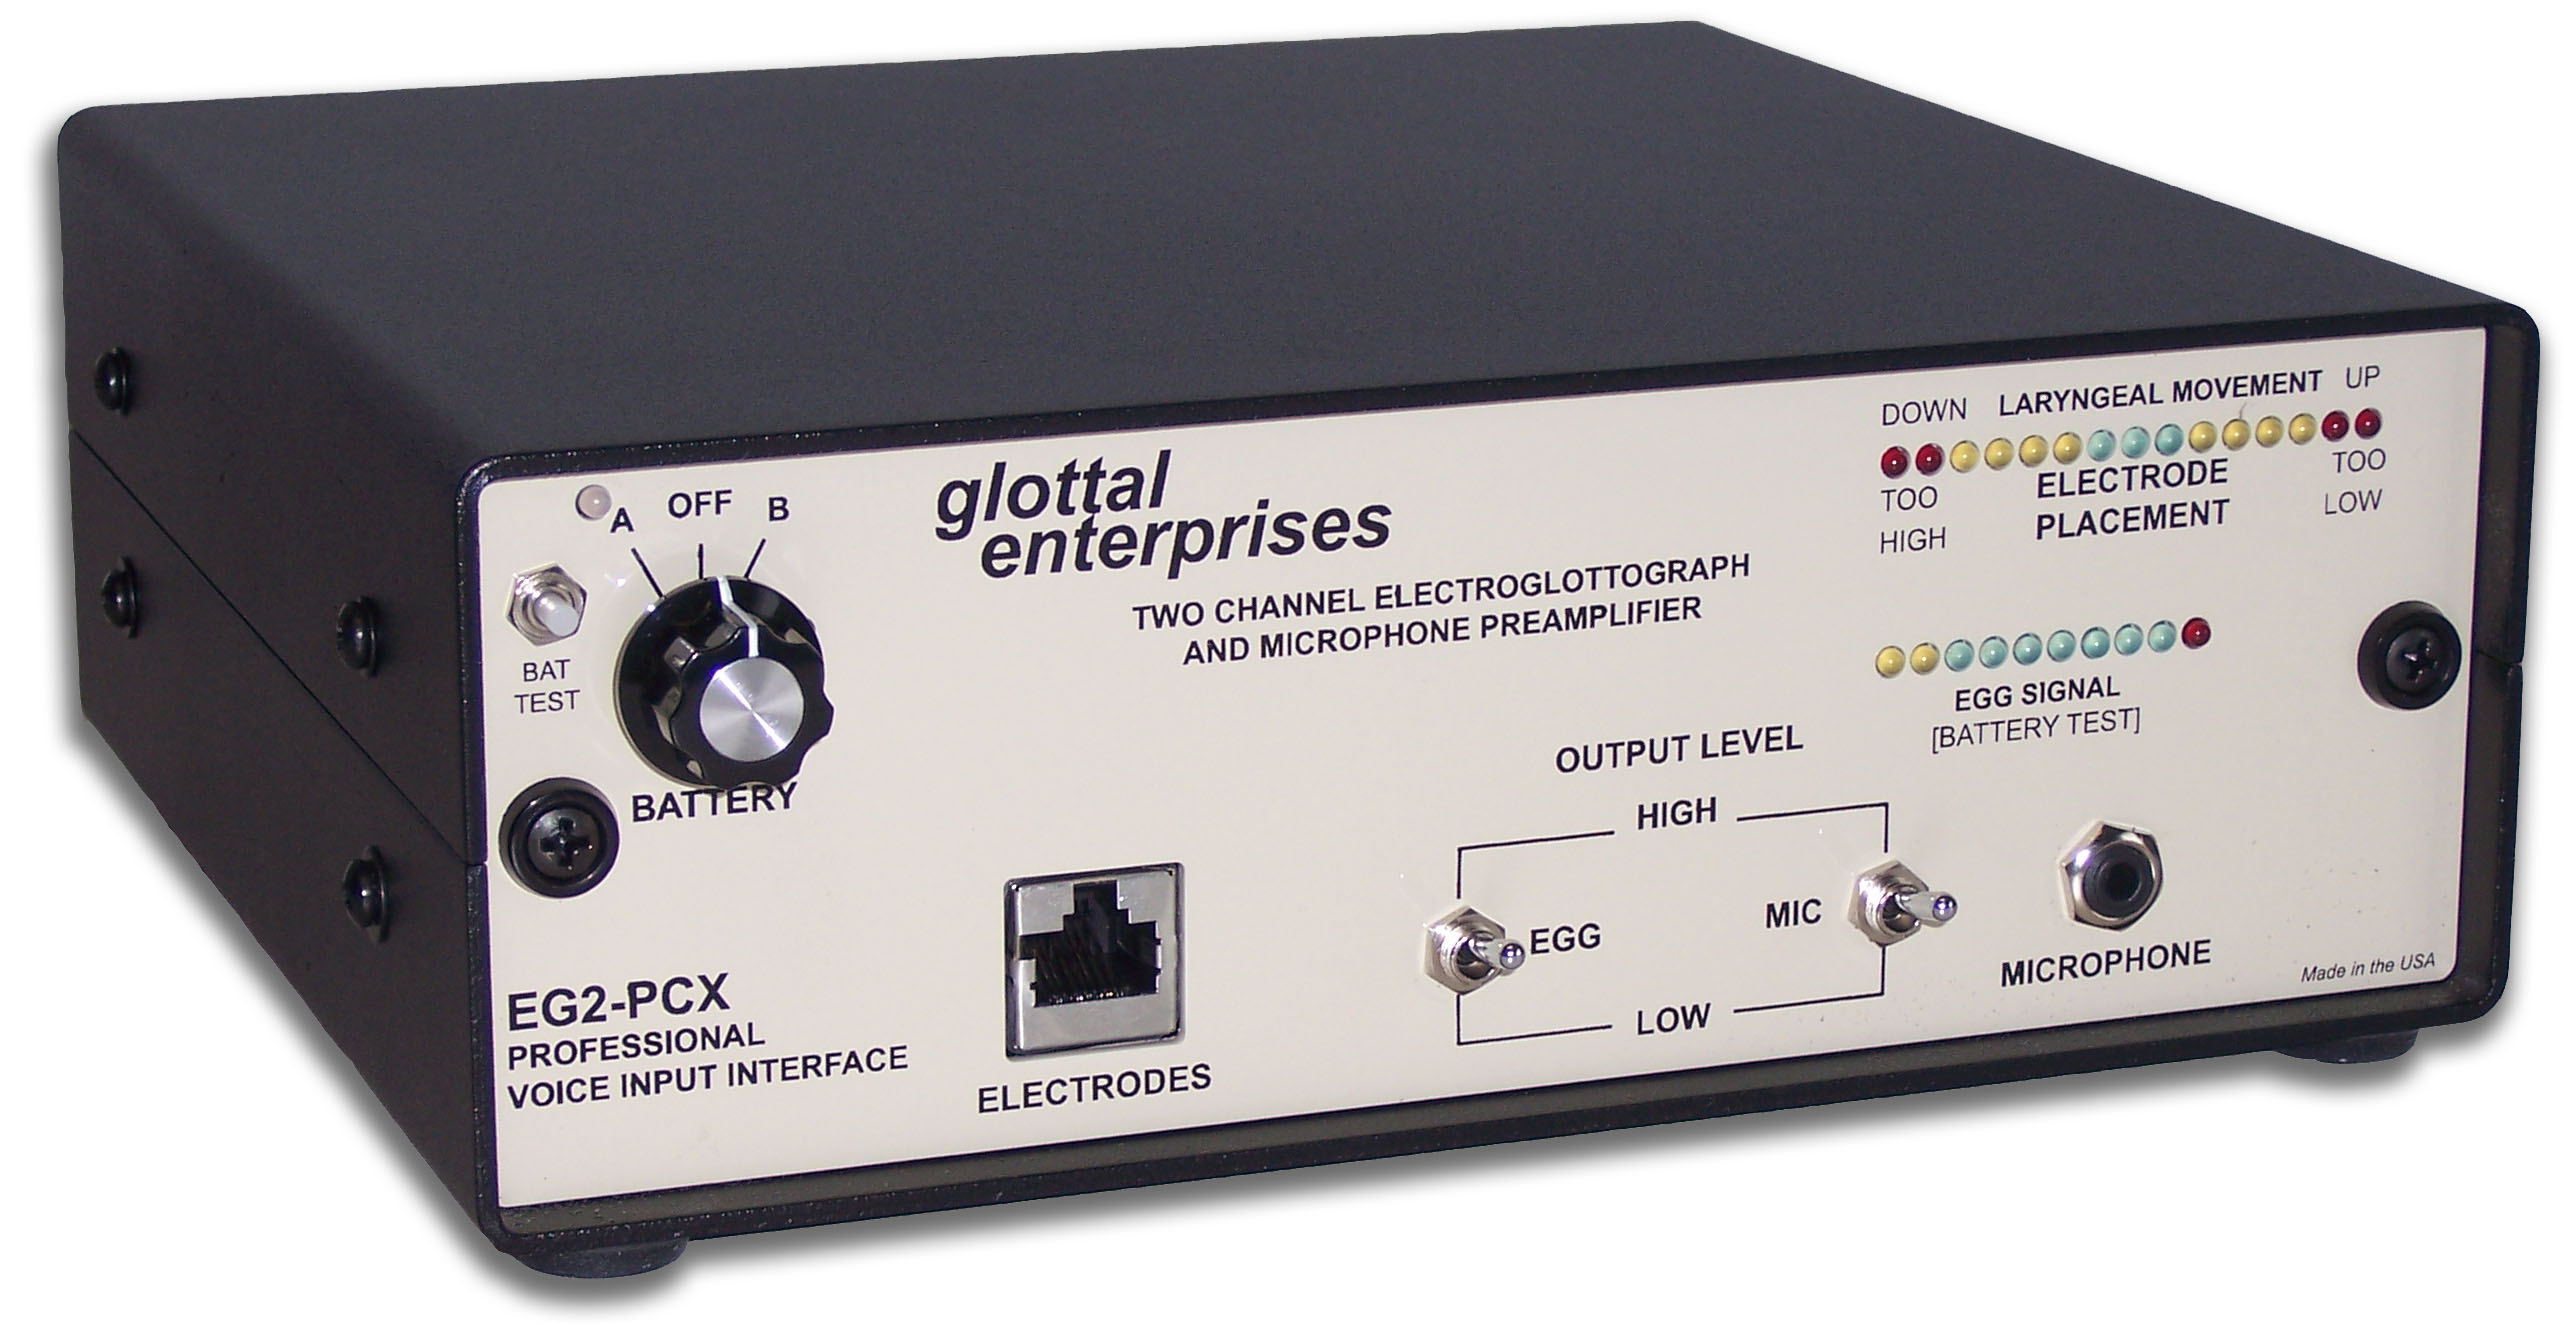
We use a Glottal Enterprises EG-2 electroglottograph for noninvasive measurement of vocal fold vibration.
Real-time vocal tract MRI
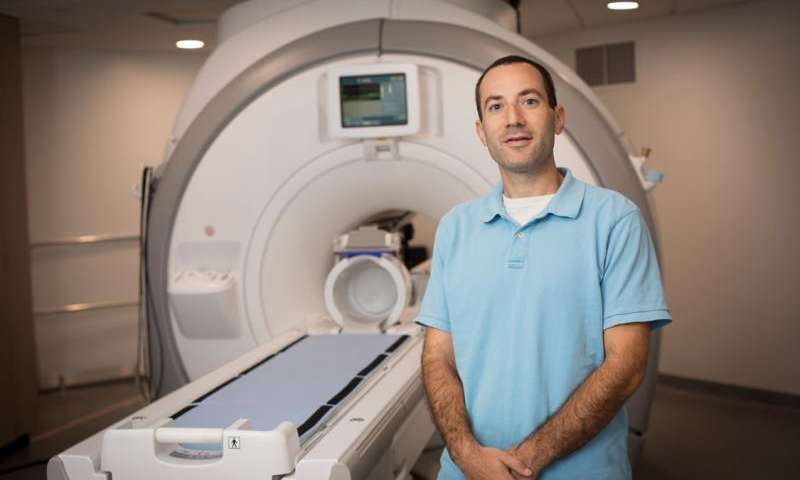
Our lab is part of the Cornell Speech Imaging Group (SIG), a cross-disciplinary team of researchers using real-time magnetic resonance imaging to study the dynamics of speech articulation.
Articulatory movement tracking
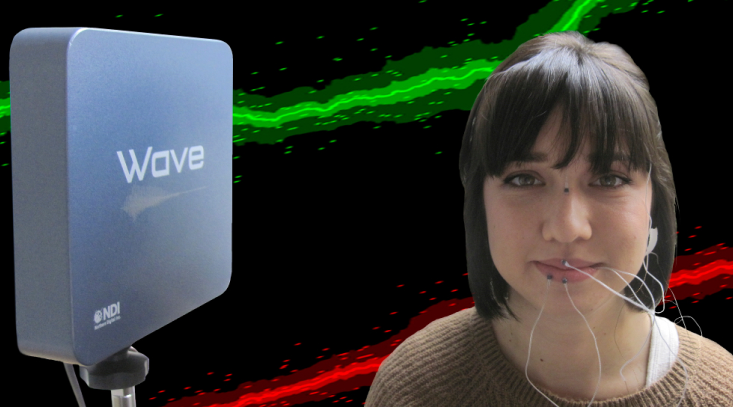
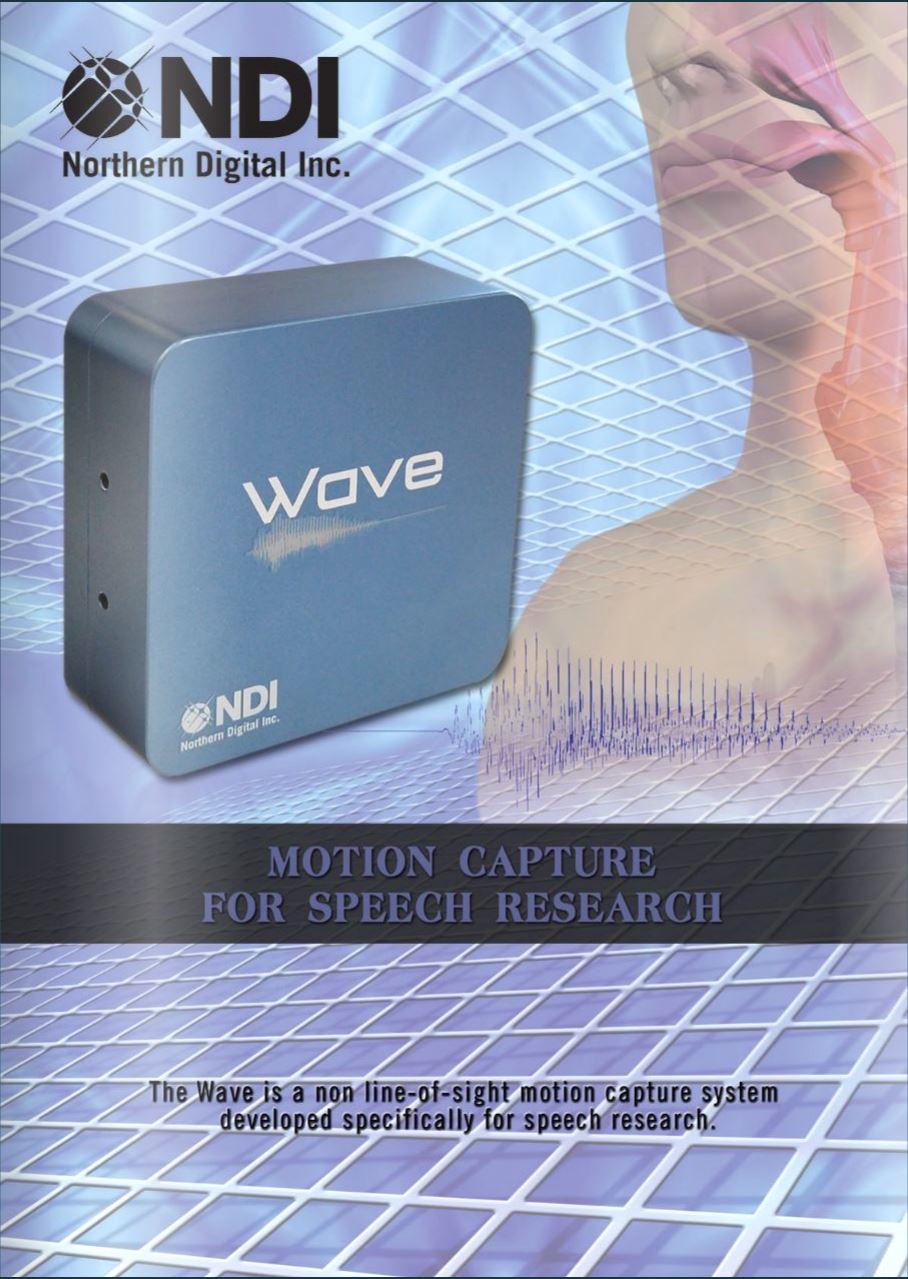
We use the Northern Digital Inc. Wave motion-capture system to study speech articulatory patterns and motor control.
Sound Booth
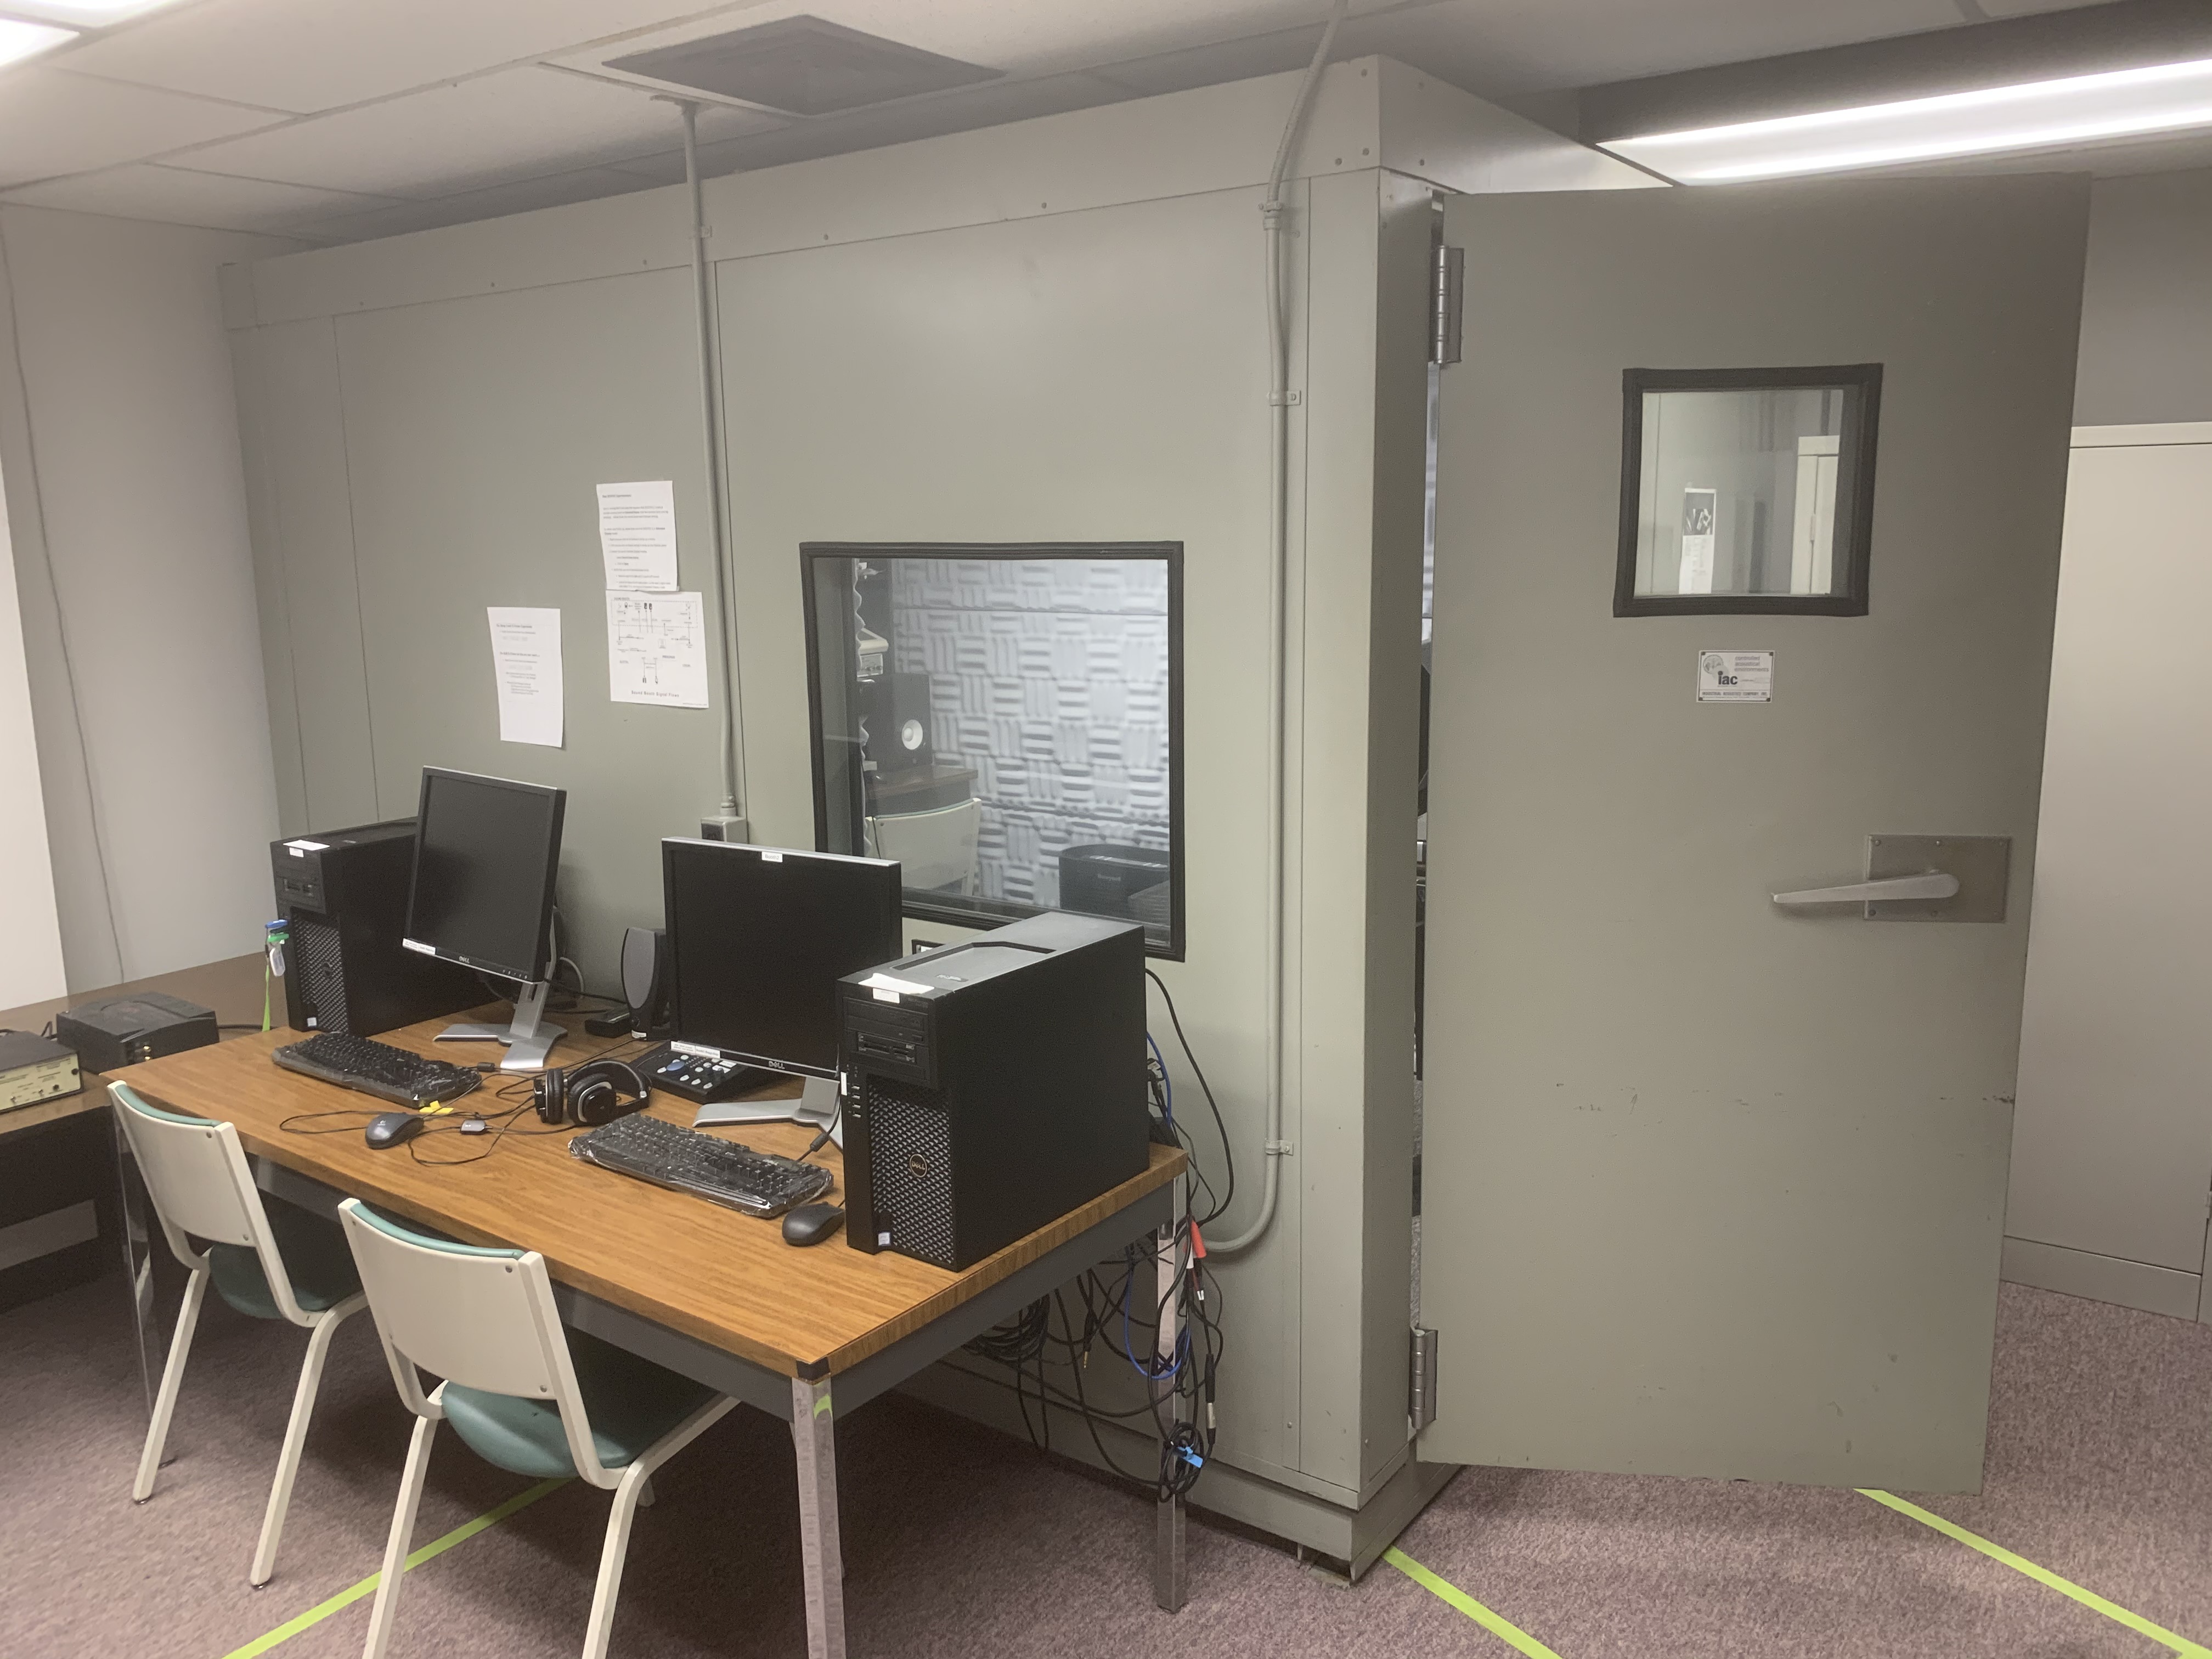
Our isolated sound recording booth serves a range of purposes--from basic recording to perceptual, psycholinguistic, and ultrasonic experimentation.
We also have the necessary software and audio interfaces to perform low latency real-time auditory feedback experiments via MATLAB and Audapter.
©Copyright 2020, Cornell University